Design: Config-File Delivery of GPU Limits
Summary
HAMi hands GPU limits to HAMi-core through environment variables. A process started from a fresh login session (SSH, su -, sudo, cron) has no such variables and runs without a limit. This design adds a limits file: the device plugin writes the limits to a file and mounts it read-only into the container, and HAMi-core reads it before anything else. The file is the default. A switch, limitDelivery, restores environment-variable delivery.
Tracking issue: #2125. Original reports: #1112, #1090.
Motivation
How limits reach HAMi-core today
During Allocate() the device plugin sets these variables on the container:
| Variable | Example | Meaning |
|---|---|---|
CUDA_DEVICE_MEMORY_LIMIT_<i> | 3000m | memory limit per allocated device |
CUDA_DEVICE_SM_LIMIT | 50 | core limit |
CUDA_DEVICE_MEMORY_SHARED_CACHE | /usr/local/vgpu/<uuid>.cache | shared region where the pod's processes account usage |
libvgpu.so itself is loaded through a file, /etc/ld.so.preload. The library reaches every process; only the values travel by environment.
Where the values are lost
An environment belongs to one process and is copied to its children. A login session is not a child of the entrypoint: sshd, su -, sudo and cron build a new environment from scratch.
| Process started by | Has the variables |
|---|---|
entrypoint, its children, bash -c, &, kubectl exec | yes |
SSH login, su -, sudo, login, cron | No |
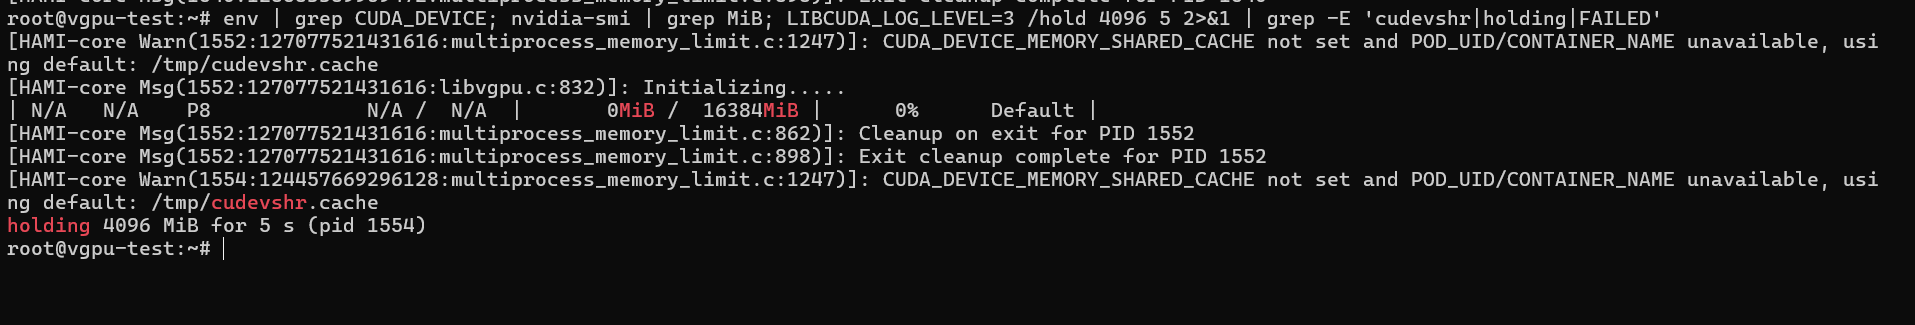
Without the variables, HAMi-core falls back to a private /tmp/cudevshr.cache and records a limit of 0, which means unlimited. The process is neither capped nor counted with the pod.
Reproduced on a current release
Kubernetes v1.35.9, containerd 2.3.4, NVIDIA driver 550.90.07, CUDA 12.4, NVIDIA A16-16Q, HAMi from the current Helm chart, pod image nvidia/cuda:12.4.1-devel-ubuntu22.04, nvidia.com/gpumem: 3000. The test program asks for 4096 MiB with cudaMalloc.
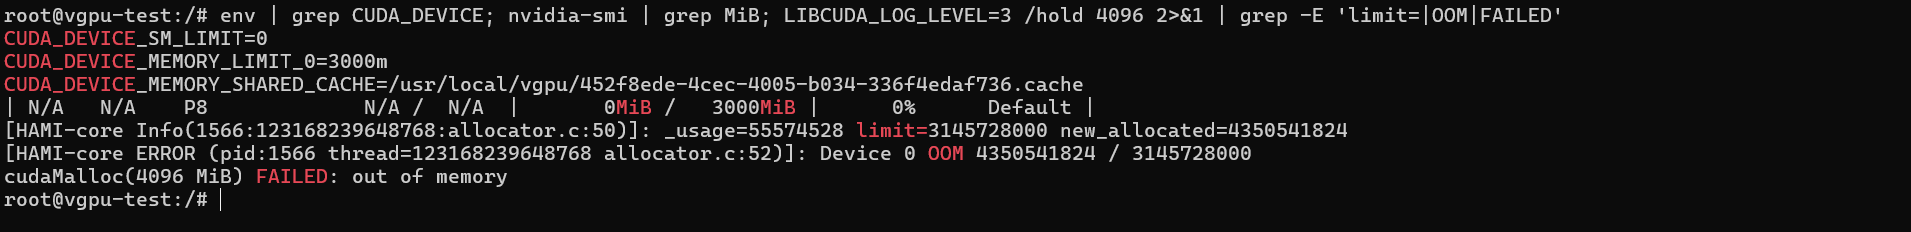
Through kubectl exec, the variables are present, nvidia-smi shows 3000 MiB, and the request is refused:
Through an SSH login in the same pod, the variables are gone, nvidia-smi shows 16384 MiB, and the same request succeeds. The library logs the fallback to /tmp/cudevshr.cache itself:
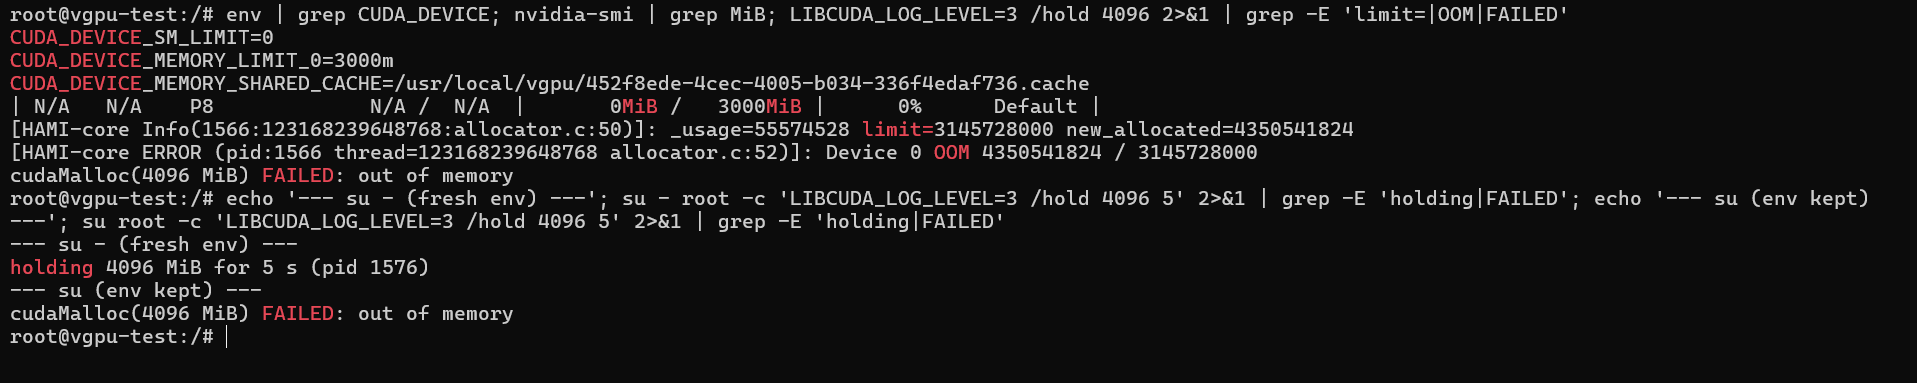
Same result without SSH: su - (fresh environment) is granted 4 GiB, su (environment kept) is refused.
A file at /overrideEnv with the right limit did not change the result on the deployed library: it is read only on the NVML path, after the shared region is already stamped. The fix is therefore about when the file is read, not only that it exists.
Decision
Deliver the values through a mounted config file, make it the default, and keep environment delivery as a switch. Environment mode is not expected to cover login sessions, operators who need that use the default.
Prior art
HAMi#3063 with HAMi-core#332 (closed) proposed the same mechanism: a per-container file beside the cache directory, mounted read-only at /overrideEnv, loaded at the start of initialized(), allocation failing on a write error, and CUDA_TASK_PRIORITY and GPU_CORE_UTILIZATION_POLICY taken from the container spec. This design adds the limitDelivery switch and rollback path, atomic publication of the file, collection of the file with the dead pod's directory, a reader that is not stopped by one bad line, and the compatibility section below.
Goals
- Every process in a container gets the same limits, however it was started.
- Delivery never depends on a process's environment, including for the location of the file.
- The file cannot be modified from inside the container.
- Old and new device plugin and HAMi-core versions can be mixed without regressions.
Out of scope, tracked separately: conflicts between processes carrying different limits (the shared region is first-writer-wins today) and protecting the shared region from a process in the container.
Proposal
The limits file
One KEY=VALUE per line, keys sorted, no comments, no blank lines:
CUDA_DEVICE_MEMORY_LIMIT_0=3000m
CUDA_DEVICE_MEMORY_SHARED_CACHE=/usr/local/vgpu/usage.cache
CUDA_DEVICE_SM_LIMIT=50
HAMI_LIMITS_FORMAT=1
It carries every variable HAMi-core reads, including the shared cache path (without it a process would enforce the limit against a private file and stay invisible to the pod's accounting) and, when set, CUDA_OVERSUBSCRIBE, GPU_CORE_UTILIZATION_POLICY, LIBCUDA_LOG_LEVEL, LIBVGPU_HOSTPID_BROKER. It also carries, from the container spec, CUDA_TASK_PRIORITY and GPU_CORE_UTILIZATION_POLICY as the webhook set them. HAMI_LIMITS_FORMAT lets a future reader recognize an older or newer file. The format is the subset HAMi-core's load_env_from_file() reads today: it stops at the first line without an =, and a plugin-written file contains no such line; JSON would add a parser to a library loaded into every process on the node.
Delivery mode
devicePlugin:
  limitDelivery: file # default; "env" restores environment-variable delivery
| Mode | Device plugin | HAMi-core |
|---|---|---|
file (default) | writes and mounts the file, and still injects the variables | reads the file first, then the environment |
env | injects the variables only | reads the environment, as before |
HAMi-core has no mode: it reads the file if present, the environment otherwise. The switch lives in the device plugin, set in the device configuration (nvidia.limitDelivery), overridable per node in the plugin config.json and per pod with hami.io/limit-delivery: "env" or "file". Resolution: pod annotation, node config, global config, default file.
Stable shared-cache name
The shared cache becomes usage.cache instead of a random UUID. The per-container host directory is already unique and recreated on every allocation, so the random name has no function, and a fixed name can be written into the file ahead of time. The vGPU monitor matches on the .cache suffix and is unaffected.
Design details
Location and mount
| Path | Mode | |
|---|---|---|
| Host | <HOOK_PATH>/vgpu/containers/<podUID>_<containerName>.limits | root-owned, 0644 |
| Container | /overrideEnv | read-only single-file bind mount |
The host file sits next to the per-container directory, never inside it: that directory is mounted read-write in the container, and a read-only bind mount only protects its own mount point. The container path is compiled into libvgpu.so (ENV_OVERRIDE_FILE, read since its first commit) and is never passed through an environment variable, because that is exactly what a login session loses.
Device plugin
In Allocate(), after the container's environment and mounts are final, in file mode only: select the variables HAMi-core reads, write them sorted to a temporary file, fsync, chmod 0644, rename over the final name (a truncated CUDA_DEVICE_MEMORY_LIMIT_0=30 would read as 30 bytes), then append a read-only mount to /overrideEnv. A write failure fails the allocation: a limit that could not be delivered must not become no limit. In MIG mode the plugin injects none of these variables and mounts neither libvgpu.so nor /etc/ld.so.preload, so it writes no file and adds no mount. The vGPU monitor removes the .limits file with the dead pod's directory.
HAMi-core
- Read the file at the start of initialization, before the shared region is chosen and the limits stamped. Both the CUDA and NVML entry points go through the same initialization.
- A file value replaces an environment value. In
filemode the file is the source of truth; inenvmode there is no file. - A change to
load_env_from_file(): today it stops at the first line without an=; instead, log the line with its number and skip it, so one bad line in a hand-edited file cannot discard the lines after it, including the cache path. - An absent file is logged at INFO and the environment is used, so bare Docker and
envmode are unchanged.
Failure behavior
| Situation | Device plugin | HAMi-core |
|---|---|---|
env mode | no file, no mount | environment only |
| MIG mode | no variables, no file, no mount | nothing to read |
| file absent (older plugin, bare Docker) | — | INFO log, environment only |
| file cannot be written | allocation fails | pod does not start uncapped |
| malformed line | never written | ERROR with line number, line skipped |
| process with no environment | — | reads the file, joins usage.cache with limits |
There is no path on which a file exists and yields no limit.
Compatibility
Environment variables stay injected in file mode, so no combination regresses. A new HAMi-core with an old plugin finds no file and behaves as today. An old HAMi-core with a new plugin does read the file, but only in nvml_preInit(), after ensure_initialized() has created the shared region: for the entrypoint the file equals the environment and nothing changes; for a login session the limit is still seeded as 0 before the file is read, so enforcement is unchanged (verified in the reproduction above). Only a new plugin in file mode with a new HAMi-core changes behaviour, and only for processes that had no limit before. Running pods keep their allocation until recreated.
Security considerations
The file is root-owned, 0644, visible inside the container only through a read-only mount, and not reachable through the read-write cache directory. This design fixes correctness for processes that lose their environment, it does not stop a process inside the container from writing to the shared region, which is tracked separately.
Implementation plan
- HAMi-core: read the file at the start of initialization, tolerant reader, tests. Useful on its own.
- HAMi device plugin: limits file writer, read-only mount,
usage.cache, unit tests. - HAMi configuration:
limitDeliveryfield, per-node override, pod annotation, Helm values, monitor cleanup. - End-to-end tests and docs:
kubectl exec,bash -c,su -,sudo, SSH, cron; configuration reference; migration note forenvmode.
Rollout and rollback
Rollout: upgrade the device plugin (default file, or env globally and file on a canary node), upgrade HAMi-core, recreate selected workloads, verify an allocation from an SSH session. Rollback: set limitDelivery: env, wait for the plugin rollout, recreate workloads; a newer HAMi-core with no file behaves as before.
Known limitations
LIBCUDA_LOG_LEVELis read before the file, so a session without environment logs at the default level.- Sandboxed runtimes (gVisor, Kata) and CRI-O need their own validation of the single-file mount.
